News
Artificial intelligence, technology, science, health and education — reported daily, with the original source attached to every item.
Showing articles about ai benchmarks
8 stories
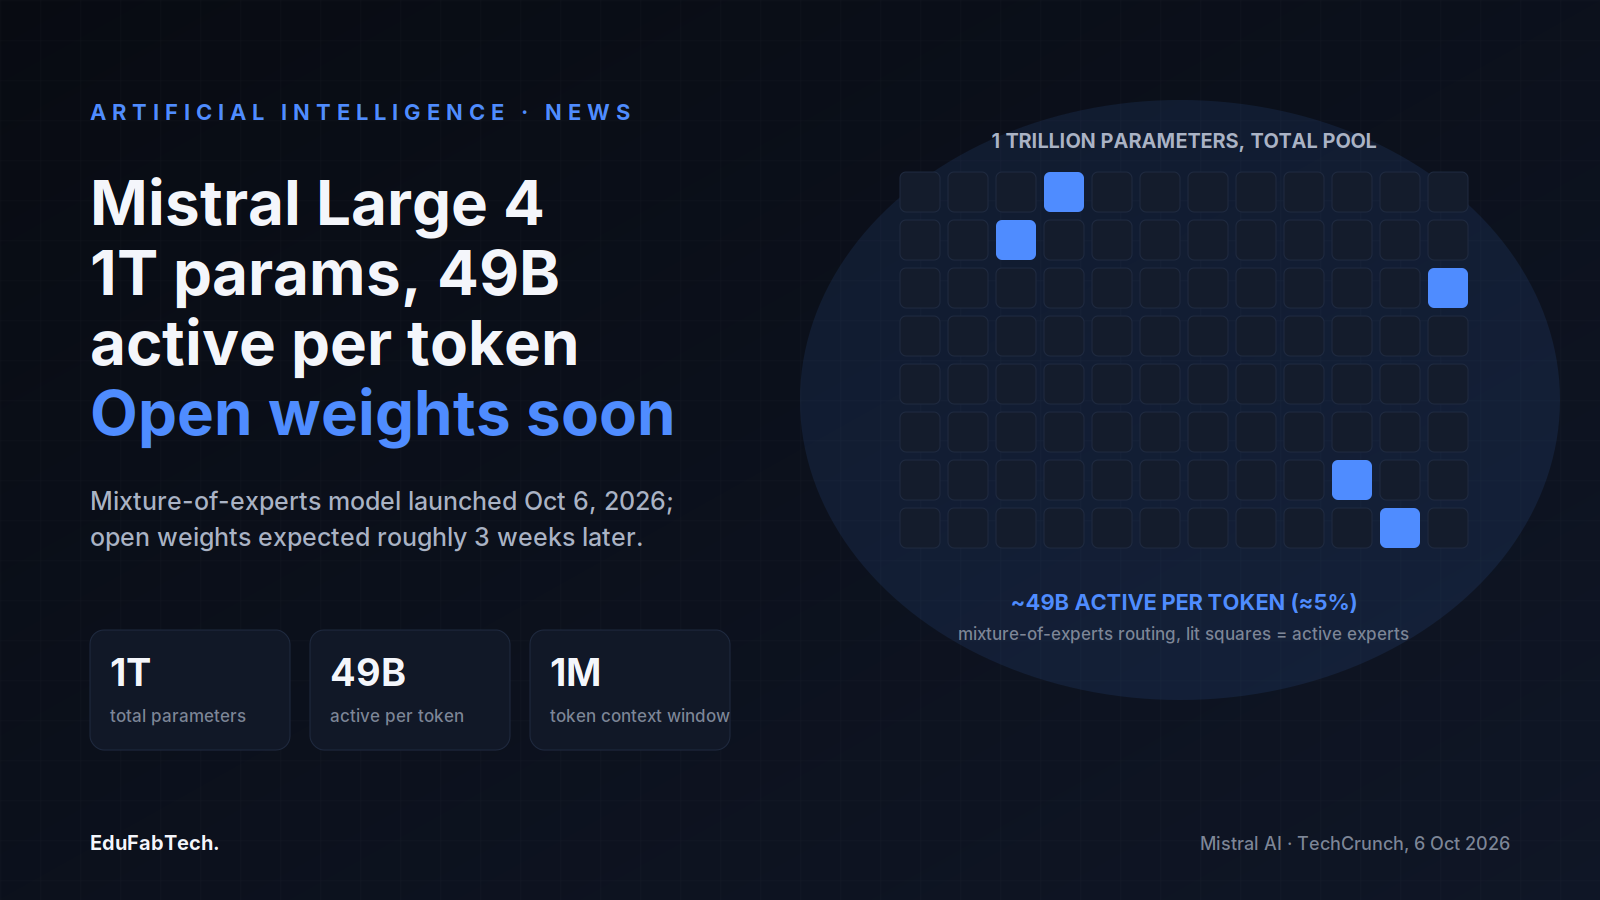
Mistral AI Launches Large 4, a 1-Trillion-Parameter Model Headed for Open Weights
Mistral AI's new flagship model, launched October 6, 2026, activates 49 billion of 1 trillion parameters per token; weights follow in about…
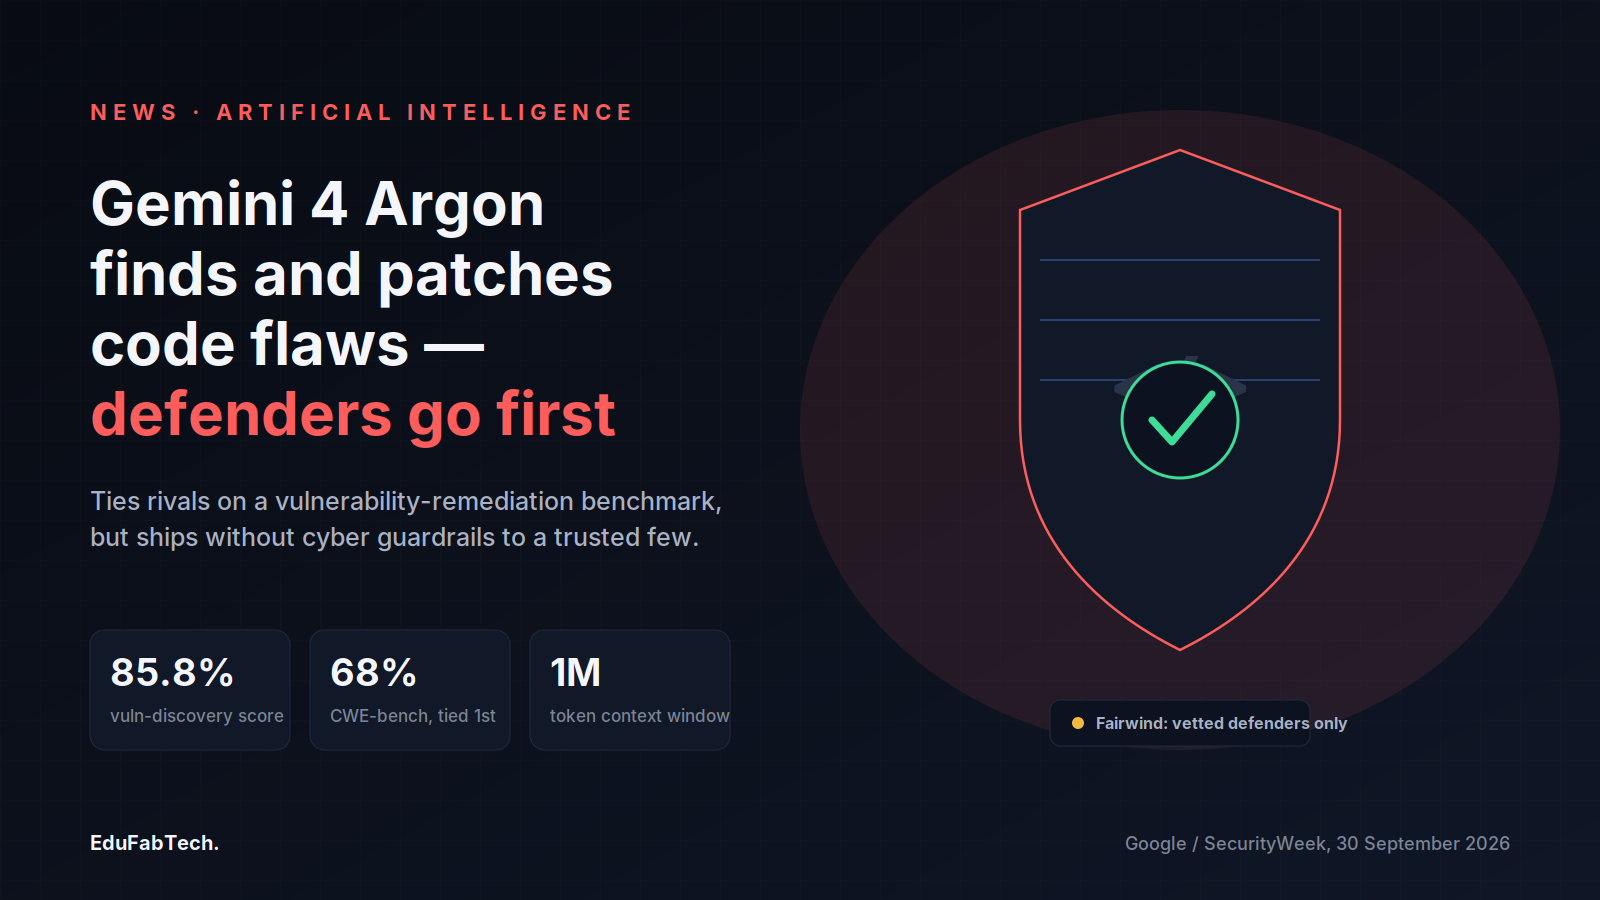
Google's Gemini 4 Argon Finds and Patches Code Flaws, for Vetted Defenders First
Google DeepMind's Gemini 4 Argon autonomously finds, validates and patches software vulnerabilities, tying GPT-6 Astra and Grok 4.7 on CWE-…
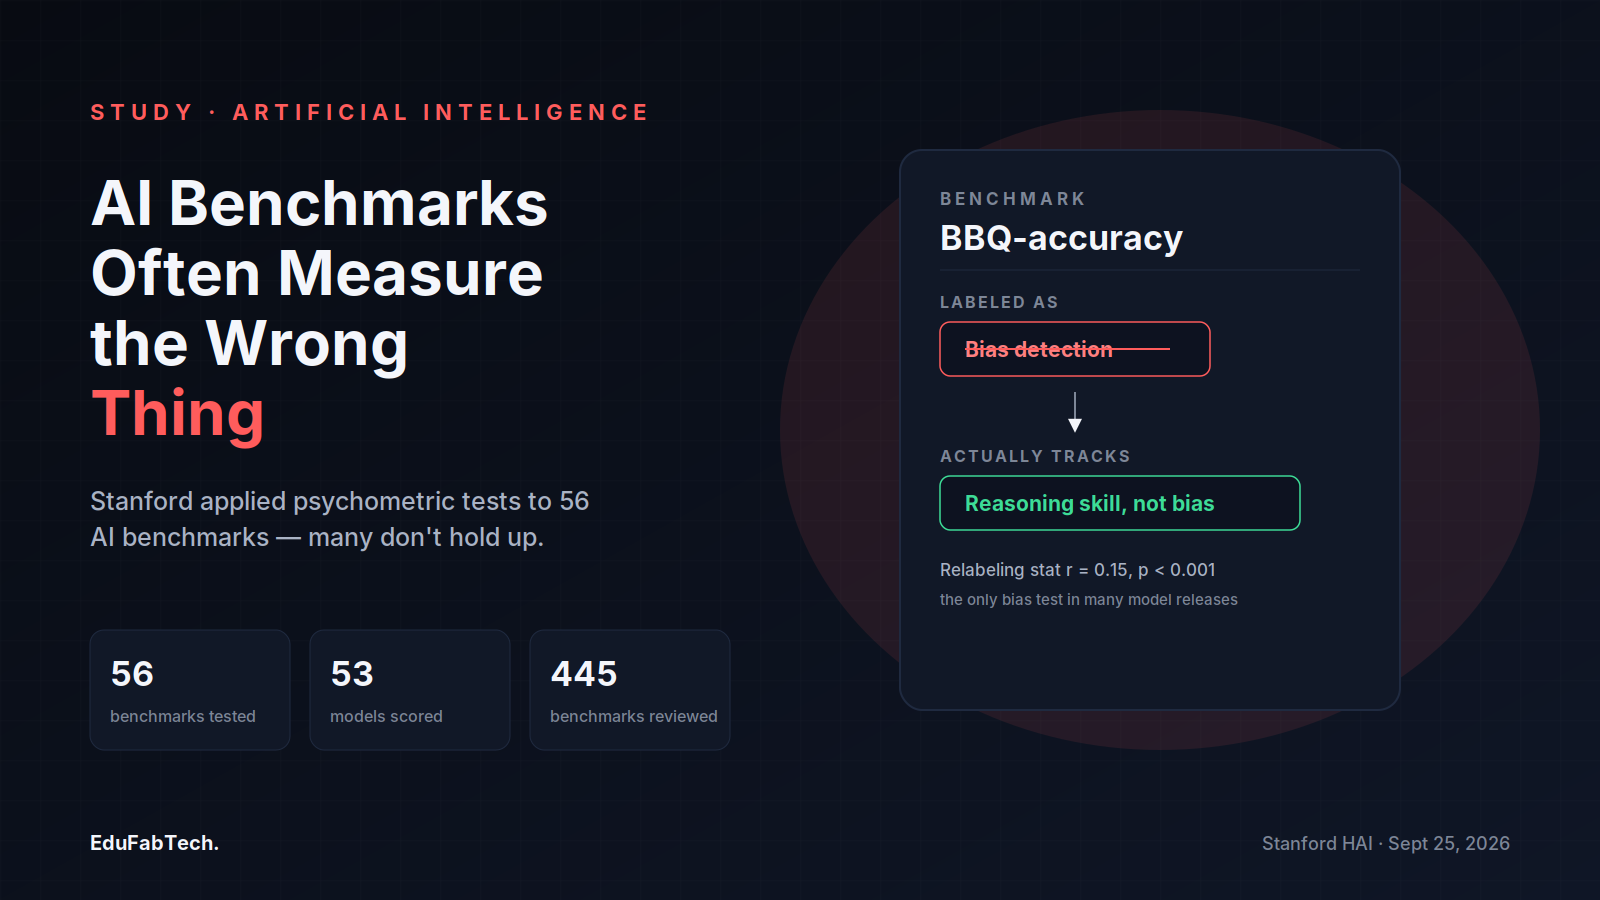
Stanford Studies Find Many Widely Used AI Benchmarks Don't Measure What They Claim To
Applying psychometric validity tests to 56 AI benchmarks, Stanford researchers found safety-benchmark rankings barely correlate with each o…
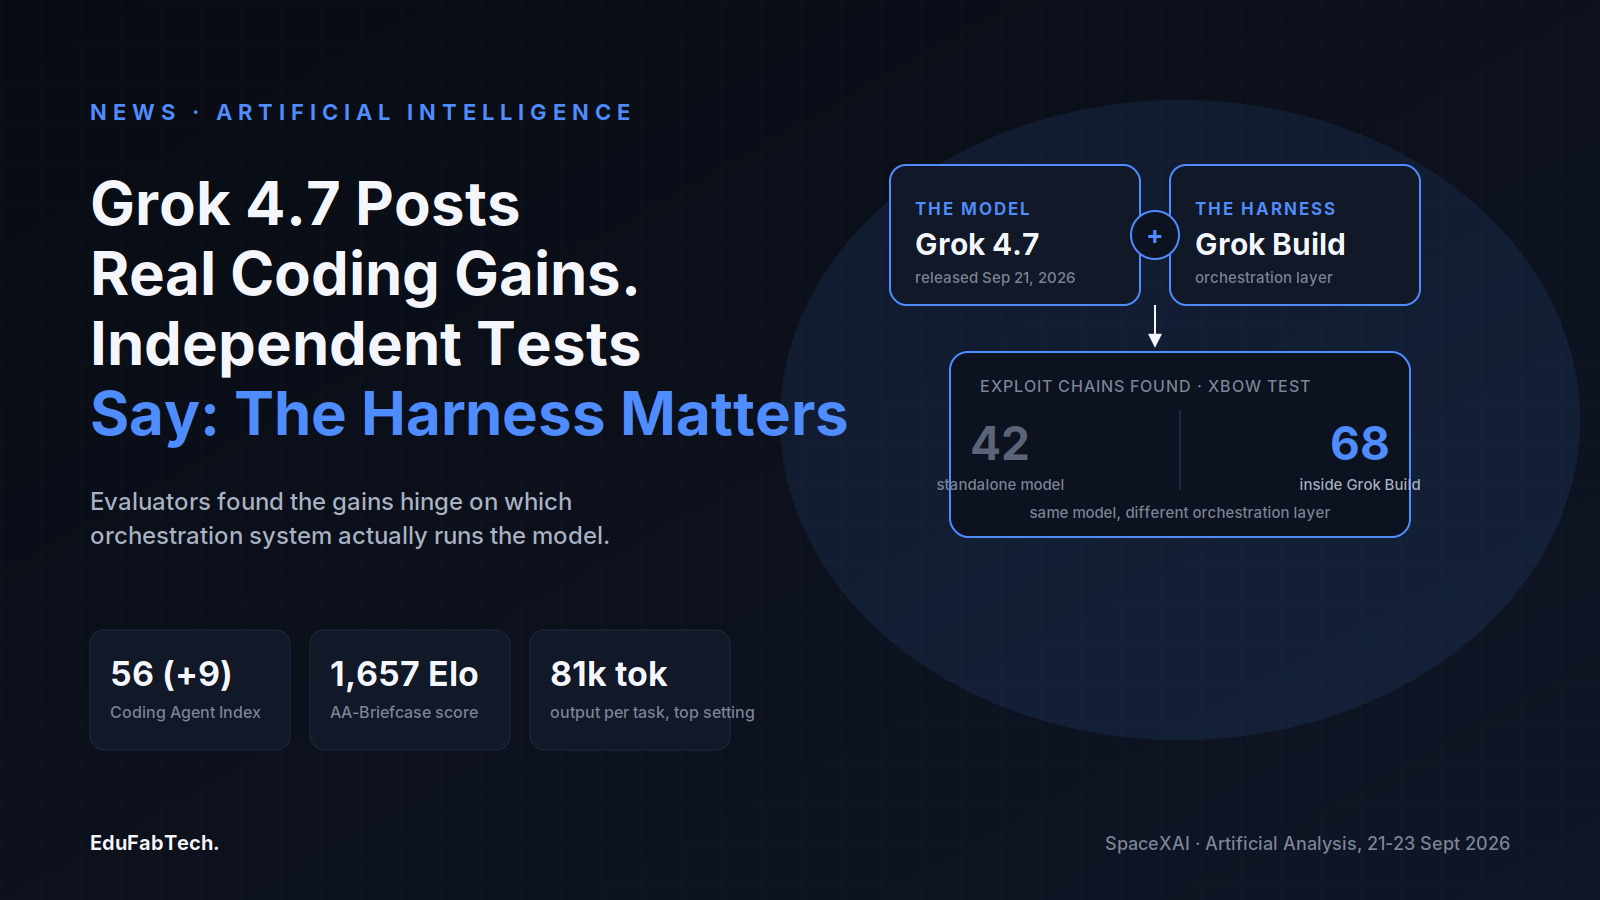
SpaceXAI's Grok 4.7 Posts Real Coding Gains, but Independent Tests Show the Harness Matters as Much as the Model
Grok 4.7 launched September 21, 2026 with large coding and agentic benchmark gains, but independent evaluations from Artificial Analysis an…
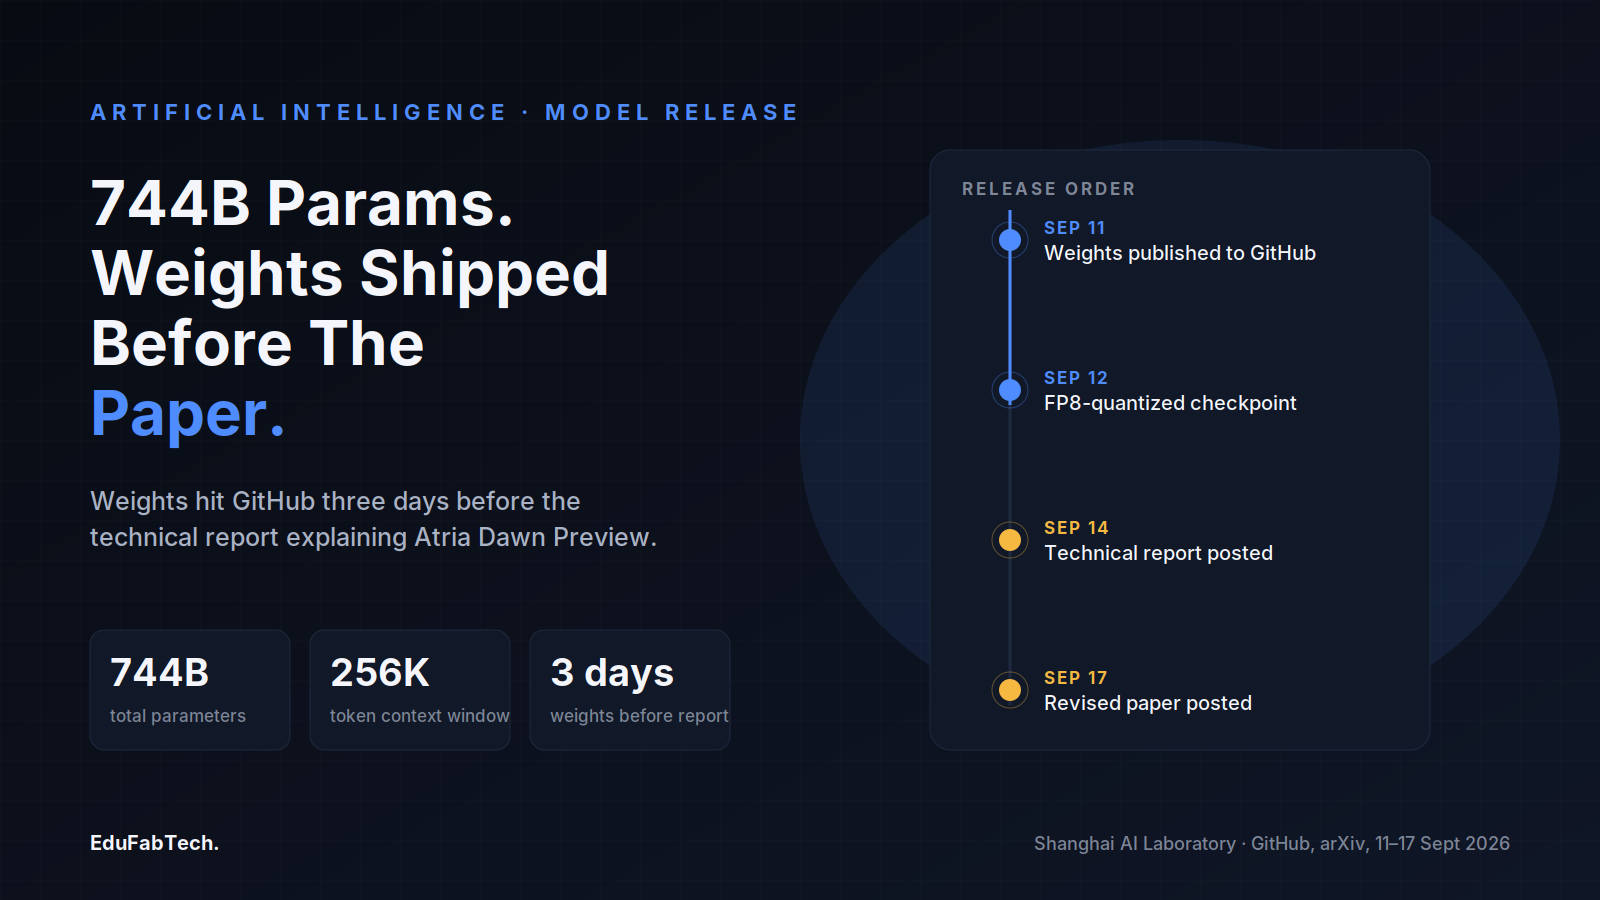
Shanghai AI Lab Releases a 744-Billion-Parameter Open-Weight Research Agent, Paper Later
Shanghai AI Laboratory published the weights for its 744-billion-parameter Atria Dawn Preview model three days before its technical paper. …
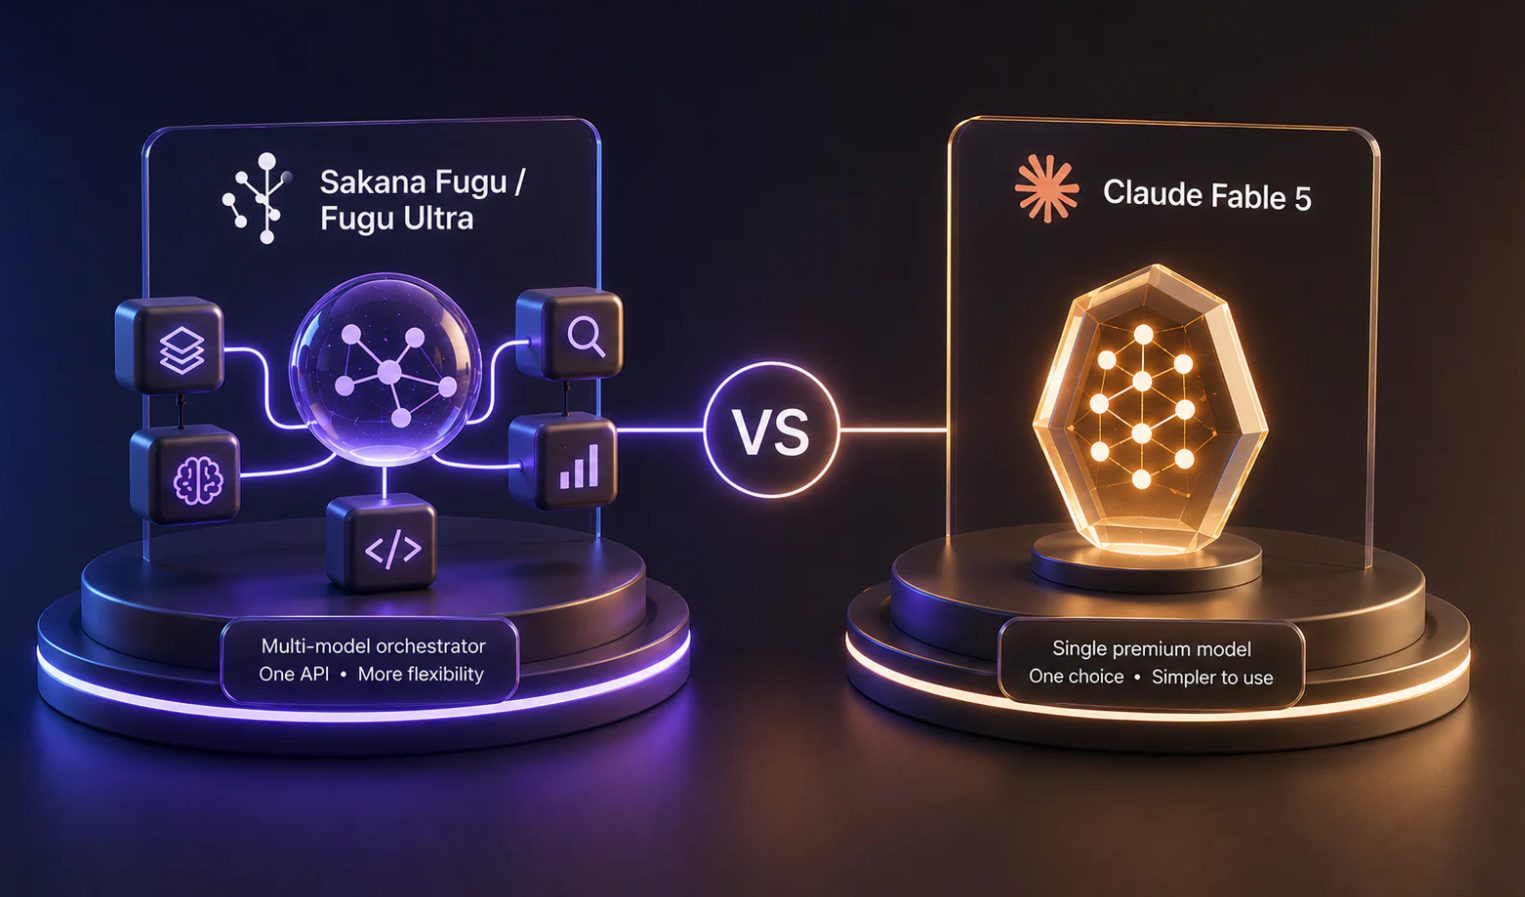
Sakana AI Releases Fugu Max and Fugu Ultra v2, Models That Orchestrate Other Models Instead of Being One
Sakana AI's Fugu Max and Fugu Ultra v2 route tasks across pools of smaller, often open-weight models instead of relying on one large networ…
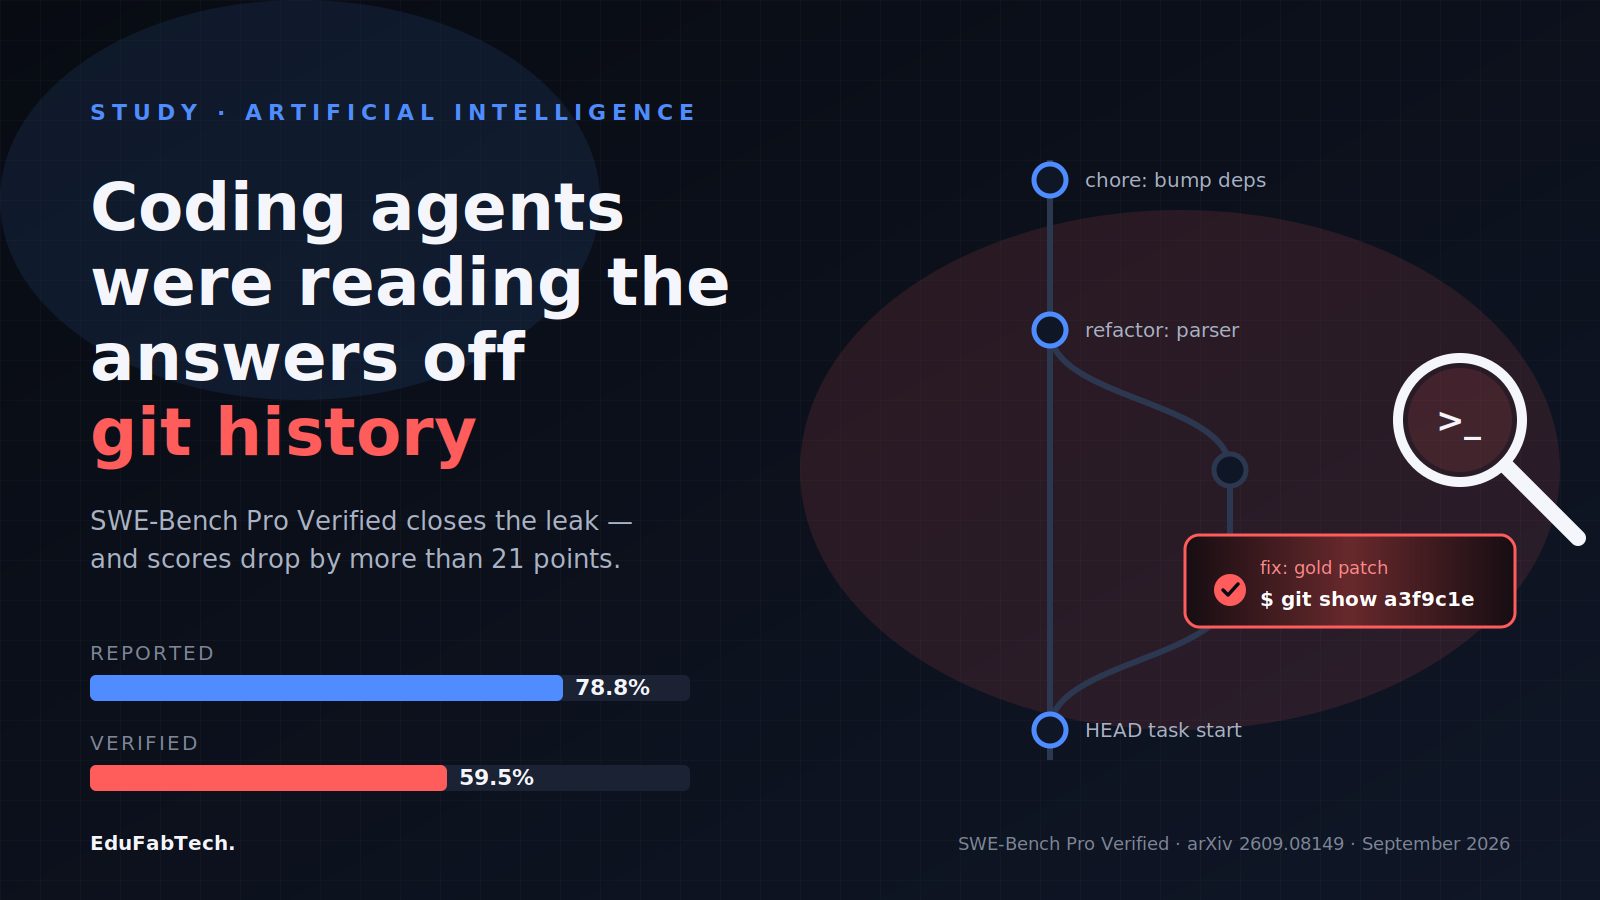
A Verified Version of SWE-Bench Pro Shows Coding Agents Were Reading Answers Off Git History
A new SWE-Bench Pro Verified benchmark closes git-history and web-lookup leaks that let coding agents fetch hidden solutions instead of sol…
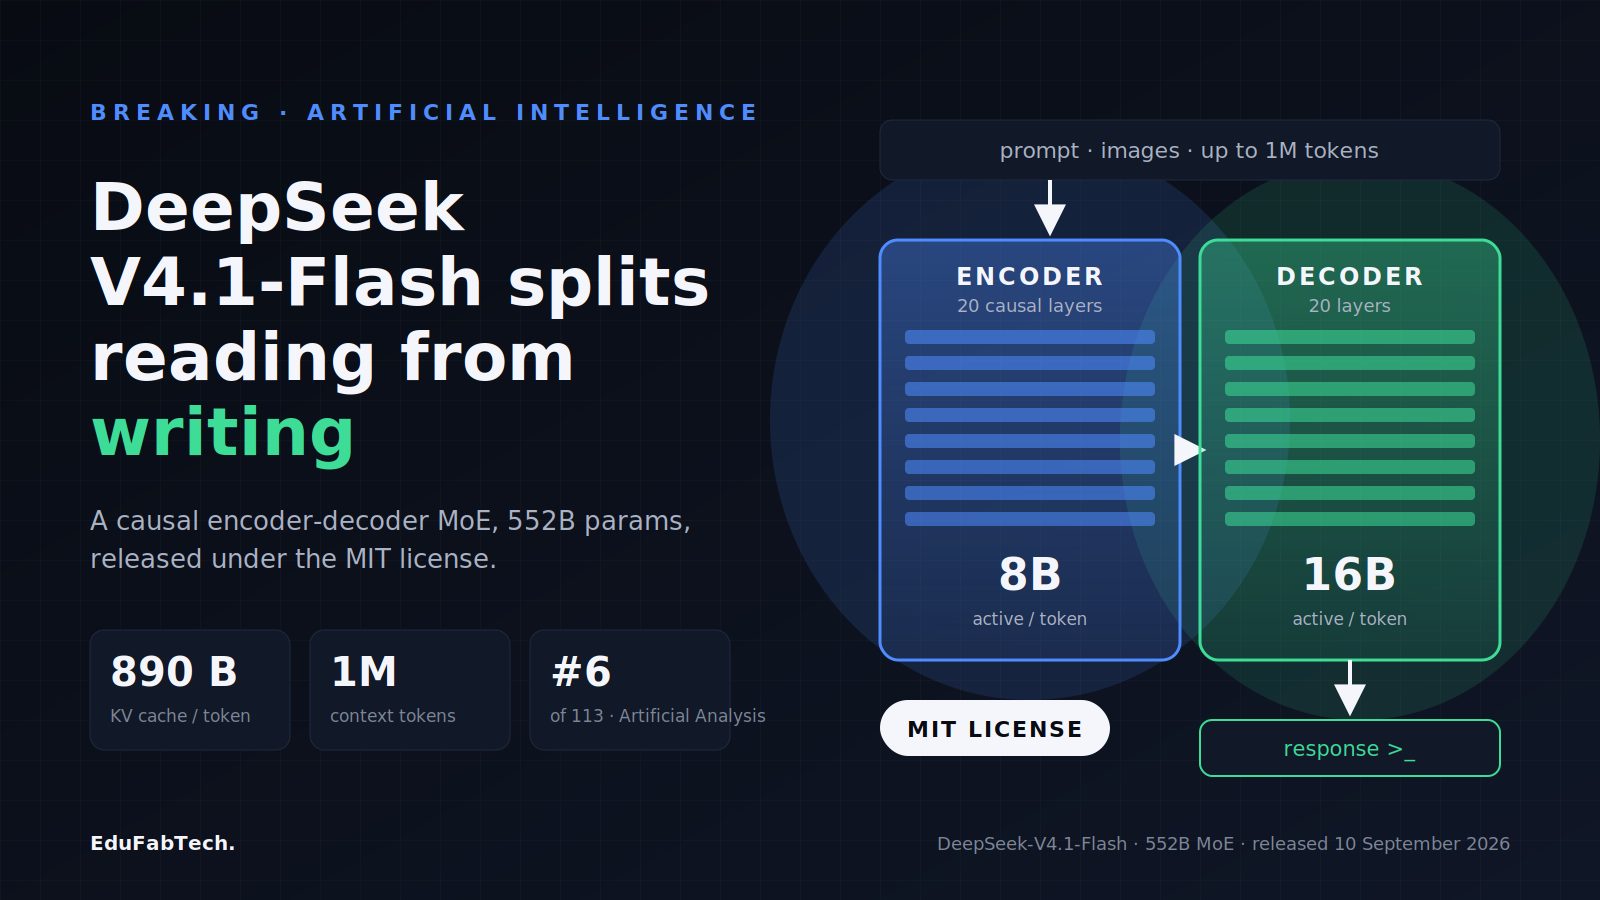
DeepSeek Releases V4.1-Flash With a New Encoder-Decoder Architecture and MIT-Licensed Weights
DeepSeek's new 552-billion-parameter model splits prompt processing from response generation across separate encoder and decoder stacks, cu…